What Duck.ai actually gets right
Start with credit, because it is deserved. Duck.ai is materially more private than opening ChatGPT or Claude directly, and DuckDuckGo documents its arrangement in unusual detail.
According to DuckDuckGo's Duck.ai privacy help page, metadata containing personal information such as your IP address is removed before the model provider is prompted, so requests to Anthropic, OpenAI, Mistral, Azure, and Tinfoil "appear as though they are coming from DuckDuckGo rather than individual users." Every provider agrees to Zero Data Retention, to never train on Duck.ai conversations, and to not share the data with third parties for their own commercial purposes. No account is required. Chats are stored locally by default, and the optional Sync & Backup feature is end-to-end encrypted with the key held only on your devices, per the Duck.ai privacy policy.
DuckDuckGo also publishes its exceptions rather than hiding them, which is worth more than most privacy marketing. We will come back to those exceptions, because they matter.
What Duck.ai is, mechanically, is a polished front door to other companies' models. The models you reach are ChatGPT models from OpenAI, Claude models from Anthropic, Mistral through together.ai, and a couple of open-weight models hosted by Tinfoil. If you want that kind of access without an account and without being profiled, Duck.ai is a genuinely good answer. This article is not an argument that it is bad. It argues that it answers a different question than the one some people think they are asking.
The distinction: who is asking, versus what was asked
Every privacy design protects something specific. Naming it precisely is the whole exercise.
An anonymizing proxy breaks the link between a request and a person. OpenAI receives your words but sees DuckDuckGo's infrastructure, not your IP, not an account, not a stable identifier. For an enormous class of questions, that is exactly right. Nobody needs to know which human asked how to deglaze a pan or what a Kubernetes sidecar is.
Local inference removes the request. The text is turned into tokens by a model file sitting in your device's storage, and the answer is computed by your own processor. There is no recipient to trust, no contract to honor, no retention window to reason about.
Now consider what happens when the content itself is the sensitive part. A therapist's session note, a merger memo naming both parties, an unreleased product spec, a patient's history, a client's settlement position, source code under NDA. Stripping your IP address from that text does not make it less confidential. It arrives at a third-party server intact, readable, and complete. The only thing anonymity changed is that the provider cannot tell which of Duck.ai's users sent it.
This is why "we never train on your data" and "we don't log your chats," both true and both valuable, do not resolve the question for regulated or contractual work. The obligation in a medical, legal, or client agreement is usually about disclosure to a third party, not about training. Transmission is the event that matters.
Privacy by policy and privacy by architecture
Here is the clearest way to compare the two designs. Ask what would have to go wrong for your content to be exposed.
With a proxy, the guarantee rests on a chain: DuckDuckGo strips the metadata correctly, the provider honors the Zero Data Retention contract, the caching window behaves as documented, the legal-retention exception is not triggered, and every one of those arrangements stays in place in the future. There is no reason today to think any link is broken. But the protection is a set of promises by organizations, and promises are subject to renegotiation, acquisition, subpoena, breach, and policy revision.
With local inference, the guarantee rests on a fact: the bytes did not leave. There is no contract to honor because there is no counterparty. An acquisition cannot change it retroactively. A subpoena to a model provider cannot produce what was never sent. Five years from now, on a device with no network, the same file still opens.
That is the real axis. Not "trustworthy company versus untrustworthy company," but privacy by policy versus privacy by architecture. Policy-based privacy can be excellent, and Duck.ai's is. Architectural privacy is simply a different category of claim, because it does not depend on anyone's continued good behavior.
"Up to one hour" is not a one-hour guarantee
This is where the policy-based nature of the protection becomes concrete, and it is worth reading DuckDuckGo's two documents side by side.
The provider table on the Duck.ai privacy help page says OpenAI and Anthropic may hold chats in short-term memory for up to one hour for prompt caching, "never written to disk." Many readers stop there and conclude the prompt ceases to exist after sixty minutes. The same table also records, for Anthropic, that chats "may be retained where required by law or as necessary to combat malicious use."
Then compare the binding Duck.ai Privacy Policy, which describes the agreements as requiring providers to delete everything "once it is no longer necessary to provide Outputs (at most within 30 days, with limited exceptions for safety and legal compliance)."
So the outer bound in the policy document is thirty days, not one hour, and both documents preserve explicit exceptions for legal compliance and abuse. These are not contradictions or gotchas. They are the normal shape of a contractual arrangement, and DuckDuckGo deserves credit for writing them down. But they do mean the one-hour figure describes ordinary caching behavior rather than a guaranteed maximum lifetime for your text.
What can a legal exception look like in practice? OpenAI's published law enforcement policy states that on a valid preservation request under 18 U.S.C. §2703(f) it will preserve user data for up to 90 days, extendable by a further 90 days, and notes that absent such a request those records may not be retained in the normal course of business. The statute sets the same 90-plus-90 structure. A preservation obligation does not care what a caching window says.
In fairness, there is a real limit on how much that matters here. Because Duck.ai proxies requests and strips identifying metadata, a provider ordinarily cannot tell which person sent a given prompt, so "produce this individual's Duck.ai chats" is not a straightforward demand to satisfy. The anonymization genuinely blunts the risk. The point is narrower and still important: Zero Data Retention means a contractual default with documented exceptions, not a technical impossibility. A local model has no exception surface at all, because there is no second party holding anything to preserve.
Free, with a meter
"Free" deserves an asterisk on both sides, so here are both.
DuckDuckGo's help pages state plainly that Duck.ai is free to use but has a daily limit on usage, that subscribers get higher daily and weekly limits, and that Pro subscribers get twice the limits of Plus. DuckDuckGo does not publish an exact message count, explaining that each model has a different cost per prompt, and there is no way to buy additional usage without a subscription. The stronger models sit behind the paid tiers: the Plus plan is $9.99 per month and Pro is $19.99 per month, both bundled with a VPN and identity services rather than sold as an AI-only plan.
On Device AI also has a paid tier, and it also has limits. The difference is what gets limited. Pro unlocks capabilities, such as certain speech models and advanced workflow features. It does not meter your conversations. There is no daily message allowance, no weekly cap, no reset at midnight UTC, and no tier that buys you more turns, because nobody is paying per token for inference that runs on your own processor. The ceiling on a local model is your hardware and your patience, and it applies equally at 3 a.m. on a plane.
One more limit worth knowing, and it is in Duck.ai's own Terms of Service rather than its privacy policy: use in regulated areas is prohibited, including "providing legal, financial, or medical advice or services," along with employment, housing, creditworthiness, educational admissions, and government decision-making. Automated querying is also prohibited, and there is no API. Read that list next to the list of people who care most about confidentiality, and the overlap is nearly total. A model running on your own Mac imposes no usage policy on your profession.
The open-weight case: you can just run it yourself
Duck.ai's most privacy-protective option routes two open-weight models through Tinfoil, and DuckDuckGo says a Trusted Execution Environment prevents Tinfoil from seeing the prompt. That is a real technical control, stronger than a contract, and it would be unfair to describe it as mere paperwork.
It is also, for those particular models, unnecessary. Open weights are open. gpt-oss-120b is in On Device AI's own catalog, alongside 70B-class models from the Llama, Qwen, and DeepSeek families and the Gemma family at several sizes. On a Mac with enough unified memory you can run that same open model yourself, in which case there is no proxy, no enclave, no attestation chain, no provider agreement, and no network dependency to reason about. The protection stops being a design you have to evaluate and becomes a fact about where the computation happened.
That is the cleanest illustration of the whole distinction. For closed models such as ChatGPT and Claude, a proxy plus contracts is the best available arrangement, and Duck.ai implements it about as well as anyone. For open models, the arrangement is optional, because you can hold the weights.
Side by side
| Question | Duck.ai | On Device AI, local model |
|---|---|---|
| Where does inference run? | ChatGPT, Claude, and Mistral on their providers' servers; two open models at Tinfoil | Your iPhone, iPad, Mac, or Apple Vision Pro |
| Does your prompt text leave the device? | Yes, anonymized | No |
| Who must be trusted? | DuckDuckGo plus the selected model provider, under contract | No one, for the local path |
| What is removed? | IP address and personal metadata; timezone, date, region and, if you opt in, city-level location are shared | Nothing is transmitted to remove |
| Works with no network? | No | Yes, after the model is downloaded |
| Account required? | No | No |
| Usage limits | Daily limit on the free tier; higher daily and weekly limits on Plus ($9.99/mo) and Pro ($19.99/mo); exact message counts not published | No message, daily, or weekly quota; Pro unlocks features, not turns |
| Best models | Top models, including Claude Opus, require the paid plans | Every catalog model is available to download; your memory decides what runs |
| Model choice | A curated list chosen by DuckDuckGo | 212 catalog models including gpt-oss-120b and 70B-class options, plus your own GGUF and MLX imports |
| Retention exposure | Documented as up to one hour of prompt caching, with the policy allowing at most 30 days and exceptions for legal compliance and abuse | None off-device |
| Usage restrictions | Terms prohibit regulated-area use, including legal, financial, and medical advice or services; no API | No usage policy governs what you do with a local model |
| Files, documents, and audio | Chat-centric, with server-side processing | Documents, transcripts, and recordings processed and indexed locally |
| Durability of the guarantee | As long as the contracts and policies hold | Permanent, because it is a property of where the computation happened |
Where local genuinely loses
A comparison that only flatters the author is not worth reading, so here is the other side.
- Raw capability on a phone. An iPhone runs models in the roughly 1B to 8B range comfortably. Those are useful for summarizing, rewriting, extraction, and ordinary questions, and they will not match a frontier model on hard multi-step reasoning.
- The Mac picture is different. This is where the comparison usually gets misrepresented, including by people arguing our side. An Apple silicon Mac with generous unified memory runs 24B and 27B models easily, 70B-class models from the Llama, Qwen, and DeepSeek families, and at the top end gpt-oss-120b at about 63 GB. That is not phone-grade AI; it is a serious workstation model running with no network. The honest statement is that the gap narrows sharply with memory rather than disappearing.
- Setup cost. Local models are downloads measured in gigabytes and you have to choose one. Duck.ai is a URL.
- Speed. A datacenter GPU is faster than a laptop, and sustained generation on a phone uses battery.
- Freshness. A local model's knowledge is frozen at training time. Web search and document retrieval exist for that reason, but it is a real difference.
Anyone claiming a 4B phone model replaces a frontier model for every task is selling something. So is anyone implying local AI means only 4B phone models. The useful question is not which side wins, but which material belongs where, and what your hardware can actually hold.
An honest note about our own cloud providers
On Device AI supports optional cloud providers, including OpenAI, Anthropic, Google, and OpenAI-compatible endpoints. They are off by default and require you to add your own key.
When you do turn one on, that path is not more private than Duck.ai. It is less anonymous. Your request goes directly from your device to the provider, carrying your own API key and your own IP address, which identifies you far more precisely than a shared proxy does. Duck.ai's architecture is the better one for anonymous access to a hosted frontier model, and we would rather say so than pretend our cloud toggle is something it is not.
The claim we do make is narrower and, we think, more useful: the default and primary path in On Device AI is local, and the local path is confidential by construction. Cloud is an escape hatch you open deliberately, per conversation, with your own credentials.
A practical division of labour
Most people are best served by using both, sorted by what the text contains rather than by brand loyalty.
An anonymized proxy is a fine default for: general knowledge, explanations, brainstorming, public-domain code, travel planning, anything you would be comfortable posting in a public forum with your name removed.
Keep it local when the material is:
- Covered by an obligation, such as client confidentiality, medical duty, legal privilege, or an export control.
- Unreleased or competitively sensitive: roadmaps, pricing, financial models, acquisition discussions.
- Personal to someone who did not consent, such as a recorded meeting containing other people's voices, or notes about a family member's health.
- Needed offline, in a facility, on a plane, or on an air-gapped machine.
- Something you will need to attest about later. "It never left the device" is a statement you can defend in an audit. "Their contract says they delete it" is a statement about someone else.
What running it locally actually gets you
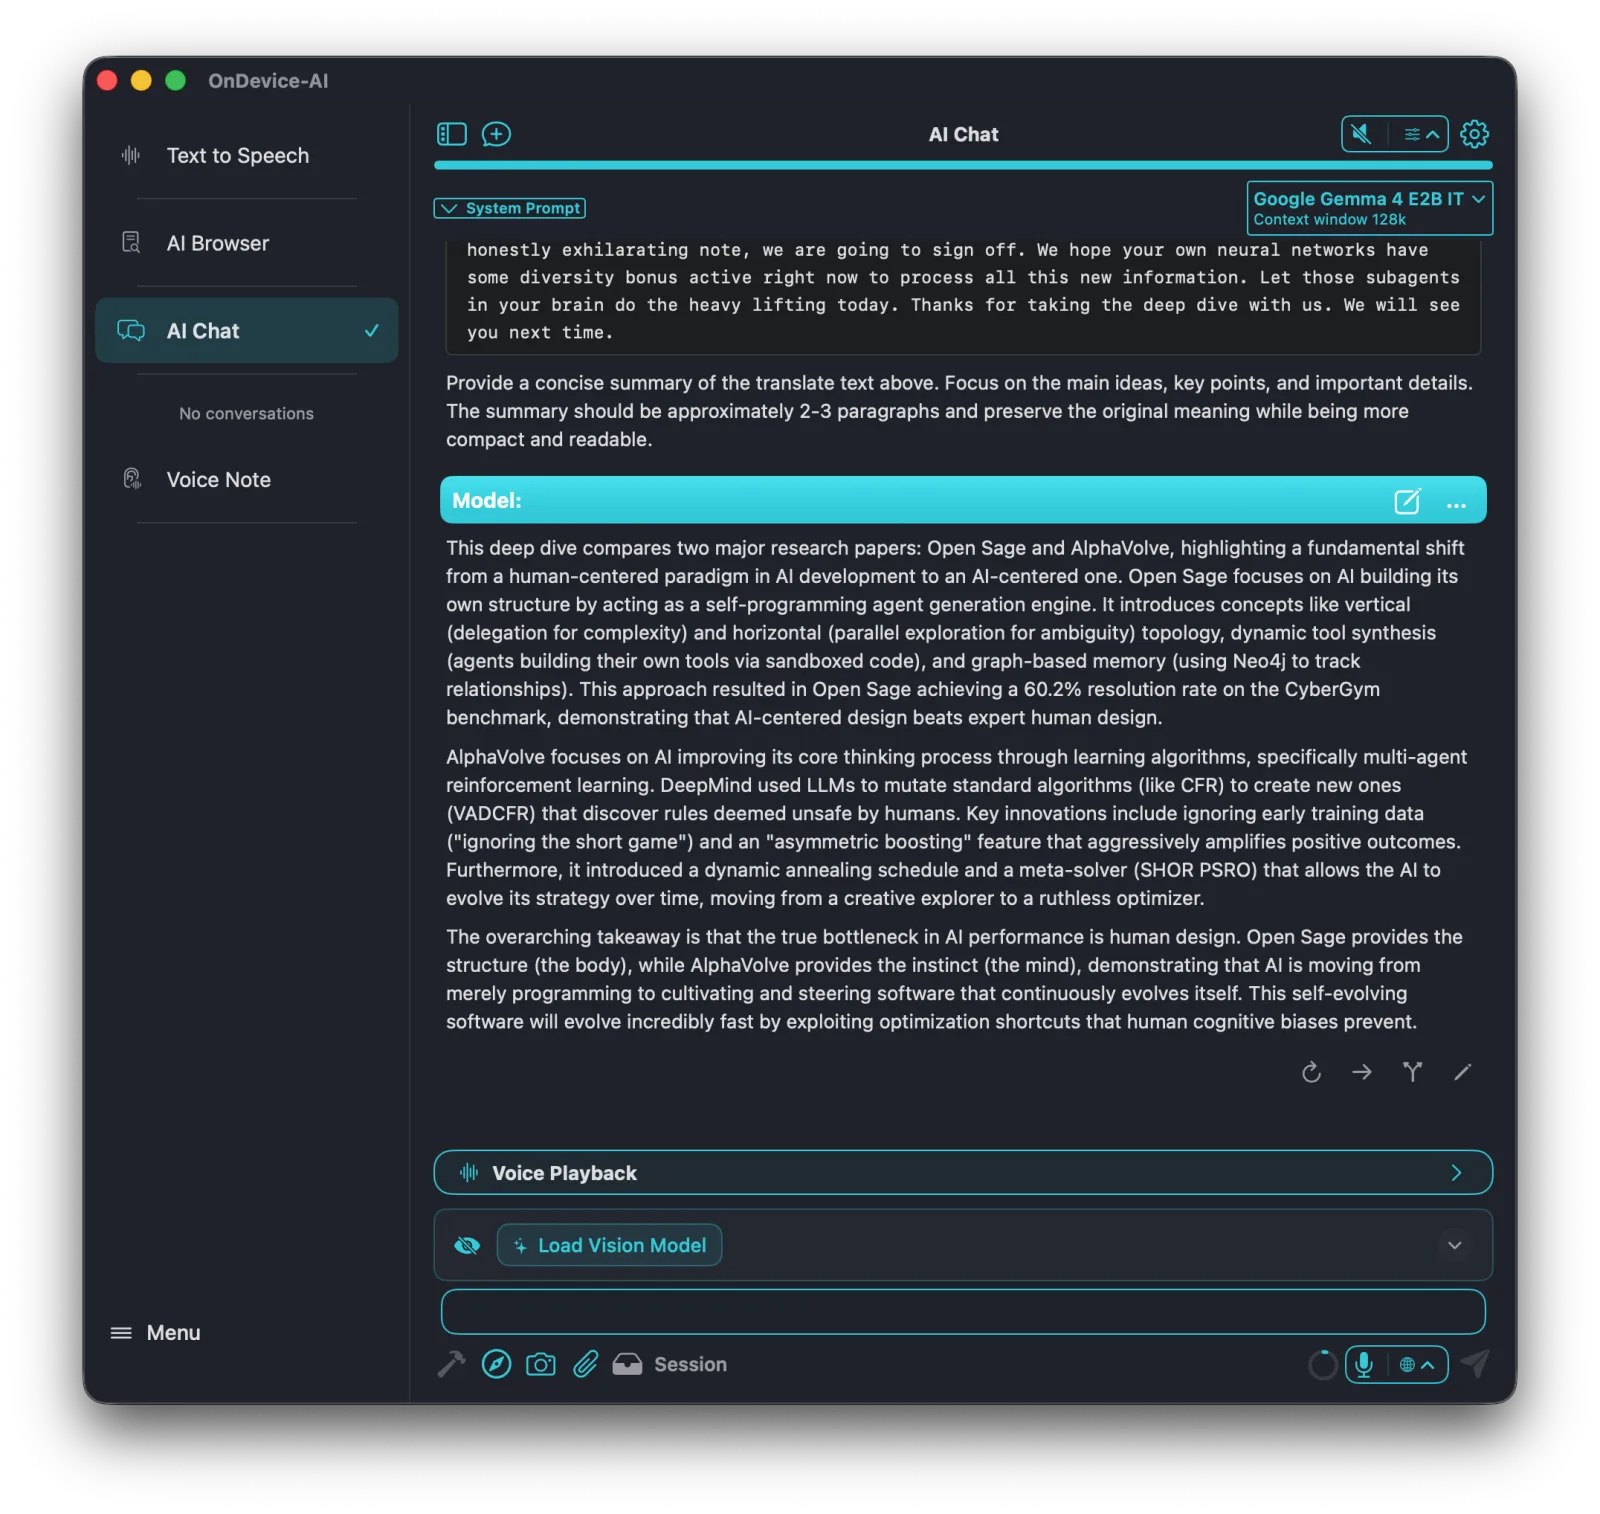
On Device AI is built around the second column of that table. It runs 212 catalog models through llama.cpp and MLX, plus your own GGUF and MLX imports, on iPhone, iPad, Mac, and Apple Vision Pro, with no account, no analytics, and no telemetry. Small models for a phone, 70B-class and larger for a Mac with the memory to hold them.
The consequence shows up in the workflows, not just the chat box. Knowledge Libraries index your PDFs and notes with local embeddings, so document questions are answered without uploading the document. Voice Notes transcribes meetings on the device, including speaker-labeled transcripts, which matters because a recording contains other people who never agreed to a third party's terms of service. Text-to-speech, OCR, and web-page extraction all follow the same rule. And when you do extend the app with external tools, MCP servers and installed skills still route every consequential action through your approval.
None of that makes Duck.ai a bad product. It makes the two products answers to different questions. Duck.ai asks how to use somebody else's model without being identified. On Device AI asks how to get the work done without sending it anywhere at all.
Frequently asked questions
Is Duck.ai private?
In a specific and meaningful sense, yes. DuckDuckGo removes metadata such as your IP address before calling the model, so requests appear to come from DuckDuckGo rather than from you, and contracts prohibit providers from training on your conversations. What it does not do is keep your text on your device. The prompt is still transmitted to a third-party provider, so Duck.ai delivers anonymity rather than confidentiality.
Does Duck.ai run AI models locally?
No. It is a front end to hosted models. Inference runs on providers' servers, including OpenAI, Anthropic, and Mistral through together.ai, with two open models hosted by Tinfoil in a Trusted Execution Environment. Chat history can be kept locally in your browser, but the model never runs on your device, which is why Duck.ai needs a connection for every message.
What is the difference between anonymity and confidentiality?
Anonymity means a third party receives your content but cannot tell it came from you. Confidentiality means the third party never receives it. A proxy provides the first; local inference provides the second. When the sensitive part is the content itself, anonymity does not protect it.
Can On Device AI work with no internet connection?
Yes, once a model is downloaded. Chat, document questions, transcription, and speech continue in airplane mode or on an isolated network.
Which is more private, Duck.ai or running a model locally?
Locally, because the prompt is never transmitted. Duck.ai anonymizes the request and still sends your text to a hosted model. A local model produces no request, so there is no retention window, no contractual exception, and no network requirement. Cloud options in any app, including our own optional providers, are a separate arrangement and are discussed above.
Does Duck.ai delete my prompt after one hour?
Not as an absolute guarantee. The one-hour figure describes ordinary prompt caching at OpenAI and Anthropic. DuckDuckGo separately documents that Anthropic chats may be retained where required by law or to combat malicious use, and its Privacy Policy sets the contractual ceiling at "at most within 30 days, with limited exceptions for safety and legal compliance." Zero Data Retention is a contractual default with exceptions, not a technical impossibility.
Is Duck.ai free, and are there usage limits?
It is free with a daily usage limit. Subscribers get higher daily and weekly limits, Pro gets twice the limits of Plus, and exact message counts are not published because cost per prompt varies by model. Extra usage cannot be bought separately, and the strongest models require Plus at $9.99 per month or Pro at $19.99 per month. On Device AI has no message quota at all; Pro unlocks features, not turns.
Can I run the same open models Duck.ai uses, locally?
gpt-oss-120b is in On Device AI's catalog, along with 70B-class Llama, Qwen, and DeepSeek models and the Gemma family. Duck.ai's Tinfoil option is a real technical protection, but open weights can be run on your own hardware, which removes the proxy, the enclave, the agreement, and the network from the picture entirely.
When is Duck.ai the better choice?
When you want frontier-model quality for free with nothing installed, and the content is not confidential. An iPhone-sized model cannot match the largest hosted models on hard reasoning, though a well-specified Mac narrows the gap considerably.
When does fully local AI matter more?
When the content is the secret, when an obligation constrains where data may travel, when the work has to continue offline, or when today's guarantee must still hold years from now regardless of any company's future policy or ownership.